MX Linux 25.1 “Infinity” is out now, restoring dual init support with both systemd and sysvinit available on a single ISO.
Monthly Archives: January 2026
Sony is handing control of its Bravia TV business to China’s TCL
Sony is ceding control of its Bravia TV brand to China’s TCL as part of a new “strategic partnership,” the companies announced in a joint press release. The Japanese electronics giant plans to sell a majority 51 percent stake in its home entertainment arm to TCL, while retaining a 49 percent share. The joint venture is set to start operations in April 2027, pending regulatory and other approvals.
The new combined business will sell TVs carrying Sony and Bravia branding while using TCL’s display technology. The partnership will also leverage Sony’s picture and audio expertise, supply chain management and other areas of expertise. For its part, TCL will contribute its vertical supply chain strength, global market presence and end-to-end cost efficiency.
“By combining both companies’ expertise, we aim to create new customer value in the home entertainment field,” Sony CEO Kimio Maki said in a statement. “We expect to elevate our brand value, achieve greater scale and optimize the supply chain in order to deliver superior products and services to our customers,” added TCL Electronics chairperson DU Juan.
The news will come as a shock to some, particularly in Japan, as Sony has been strongly associated with high-quality TVs since the Trinitron days. However, it’s currently fighting in a low-margin TV business full of formidable competitors including Samsung, LG, Hisense and TCL. The company has already sold off or closed other electronics operations, including PCs and tablets, and is barely hanging in with its smartphone business.
Sony effectively stopped making its own LCD and OLED panels some time ago, while TCL has increased its own production — having recently purchased LCD Panel patents from Samsung and taken over its plant in China. Other Japanese companies like Toshiba and Hitachi have already exited the TV business, while some including Panasonic have a highly reduced presence.
The Bravia brand survived mainly thanks to customers willing to pay extra for high-end picture and sound quality, along with Sony’s association to filmmaking and high-end camera gear. As I detailed in a recent explainer, Sony was a pioneer in many key flat panel breakthroughs, having developed LED backlighting, quantum dot technology and the first OLED TVs.
This article originally appeared on Engadget at https://www.engadget.com/home/home-theater/sony-is-handing-control-of-its-bravia-tv-business-to-chinas-tcl-120957252.html?src=rss
LEGO Art Love Collectible Set Drops to an All-Time Low Since Launch Ahead of Valentine’s Day, Already Flying Off Shelves

It’s time to look beyond flowers or chocolates.
The post LEGO Art Love Collectible Set Drops to an All-Time Low Since Launch Ahead of Valentine’s Day, Already Flying Off Shelves appeared first on Kotaku.
How to put data first in K–12 AI education by using data case studies
In Germany, as in many countries, AI topics are rapidly entering formal computer science education. Yet, this haste often risks us focusing on fleeting technological developments rather than fundamental concepts. As computer science educator Viktoriya Olari, from Free University of Berlin, discovered in her research, the fundamental role of data, which powers most modern AI systems, is critically underestimated in many existing frameworks. If students are to become responsible designers of such systems, they can’t afford to treat AI as an opaque box. Rather, they must first master the messy, human process that begins with the data itself.
In our October research seminar, Viktoriya shared the results of her work over the last four years on how schools can shift the focus from the latest technologies to the underlying data. Her research offers a clear structure for what young people should learn about data and how teachers can make it work inside ordinary classrooms.
Why begin with data?
Viktoriya’s analysis of existing AI education frameworks found the data domain is underrepresented, with essentials such as data cleaning often not addressed at all. She argues that, because modern AI systems are data driven, students need both language and routines for working with data: being able to name concepts like training vs test data, data quality, and bias, and to explain practices such as collection, cleaning, and pre-processing. That’s the rationale for teaching data concepts and practices first, and then placing modelling inside an explicit, staged lifecycle.
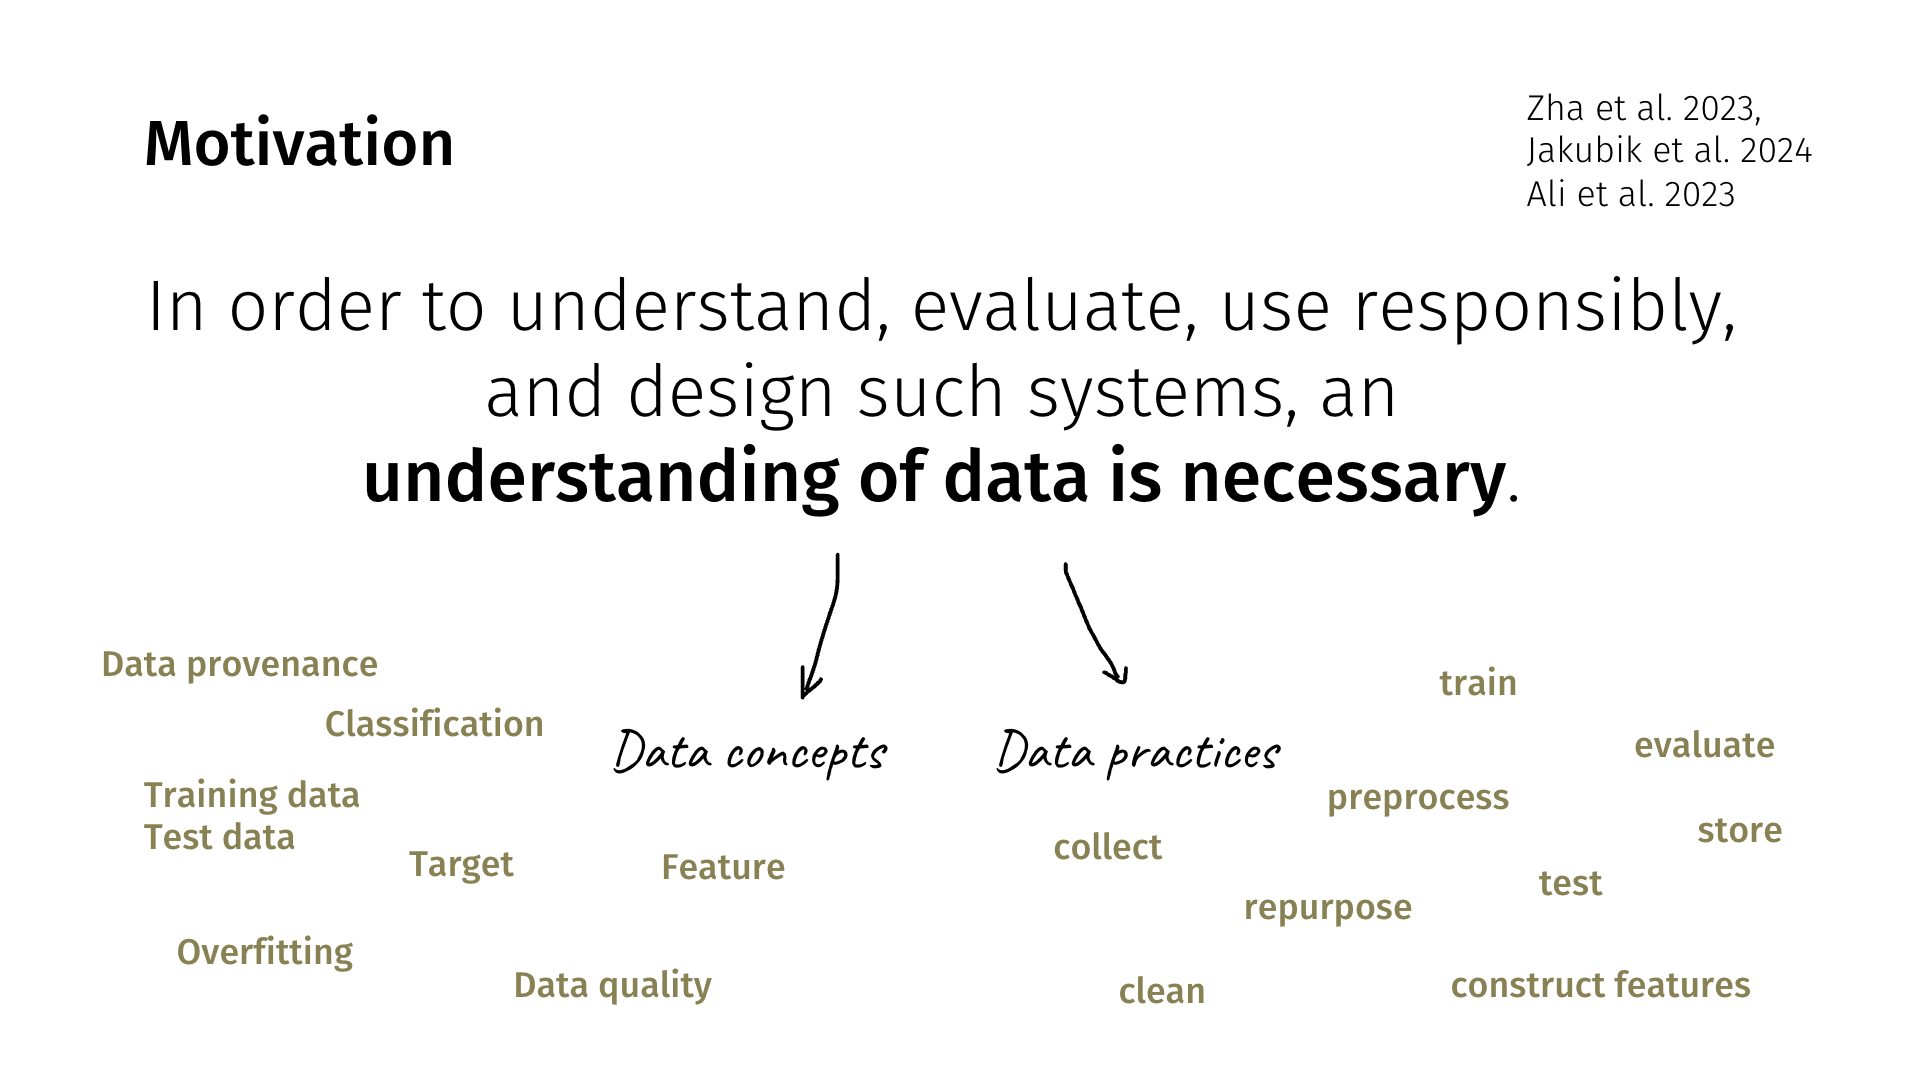
Her talk presented this argument in the German school context, where AI topics are entering state curricula quickly. Her critique targets how existing frameworks fail to address data and how that gap undermines responsible evaluation and design. The proposed model centres data by pairing an eight-stage, data-driven lifecycle with a curated set of key concepts and practices, and by making “data-based judgment skills” a key outcome.
Viktoriya’s work organises this understanding into two foundational components: data concepts (the vocabulary, e.g. training/test data, data quality, overfitting) and data practices (the actions, e.g. collect, clean, train, evaluate).
A lifecycle for learning
Viktoriya’s framework is built around an eight-stage data lifecycle, stretching from defining a task through gathering, preparing, modeling, evaluating, and finally sharing or archiving results. Inside that backbone she has identified two layers of learning targets:
- Data concepts – roughly a hundred ideas that give teachers and students a common language, from “training vs. test data” and “bias” to “features”, “labels”, and “provenance”.
- Data practices – 28 kinds of hands-on work (and 69 subpractices) that materialise those ideas: for instance collecting, cleaning, splitting datasets, checking quality, training and evaluating models, and handling privacy and deletion responsibly.
More details are available in her work on data-related concepts and practice.
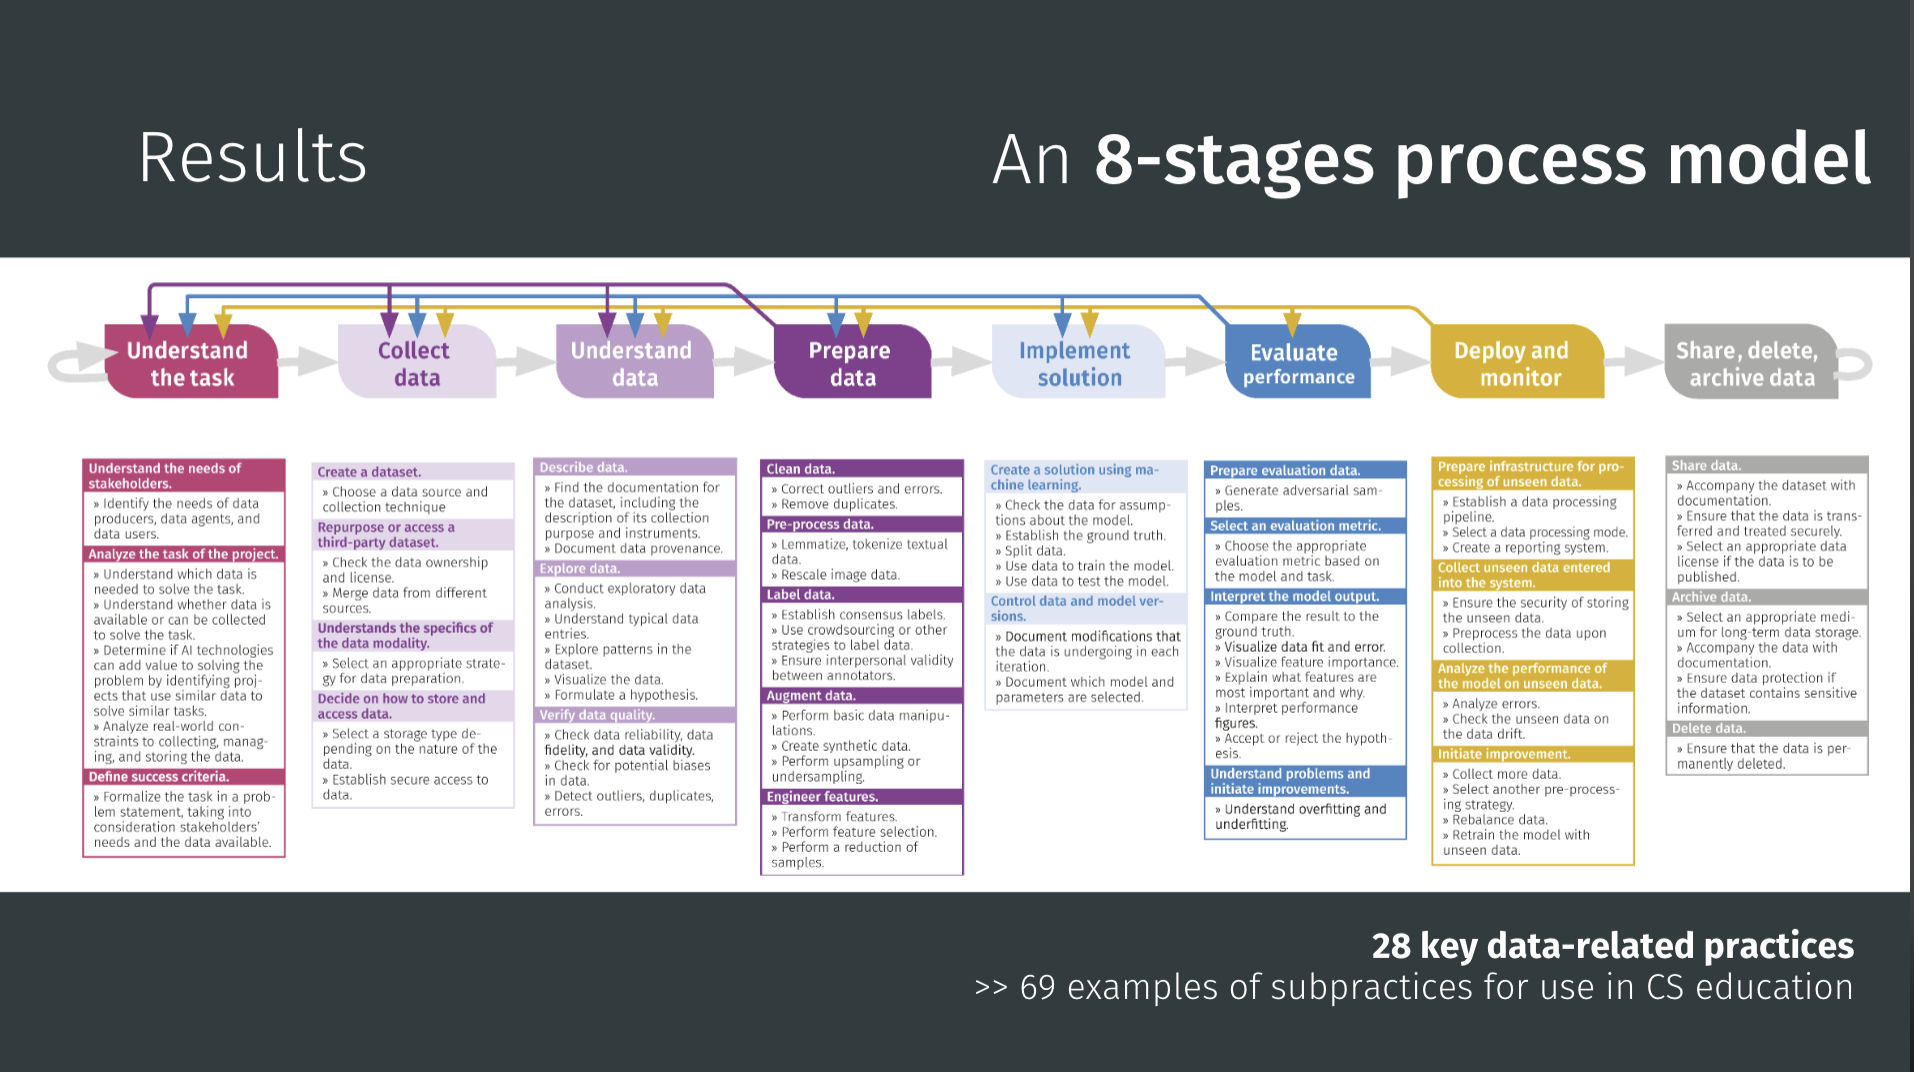
Viktoriya’s 8-stage process model of the data-driven lifecycle. It serves as a guide for curriculum developers and teachers, outlining 28 key data-related practices and providing 69 examples of subpractices for use in K–12 computer science education.
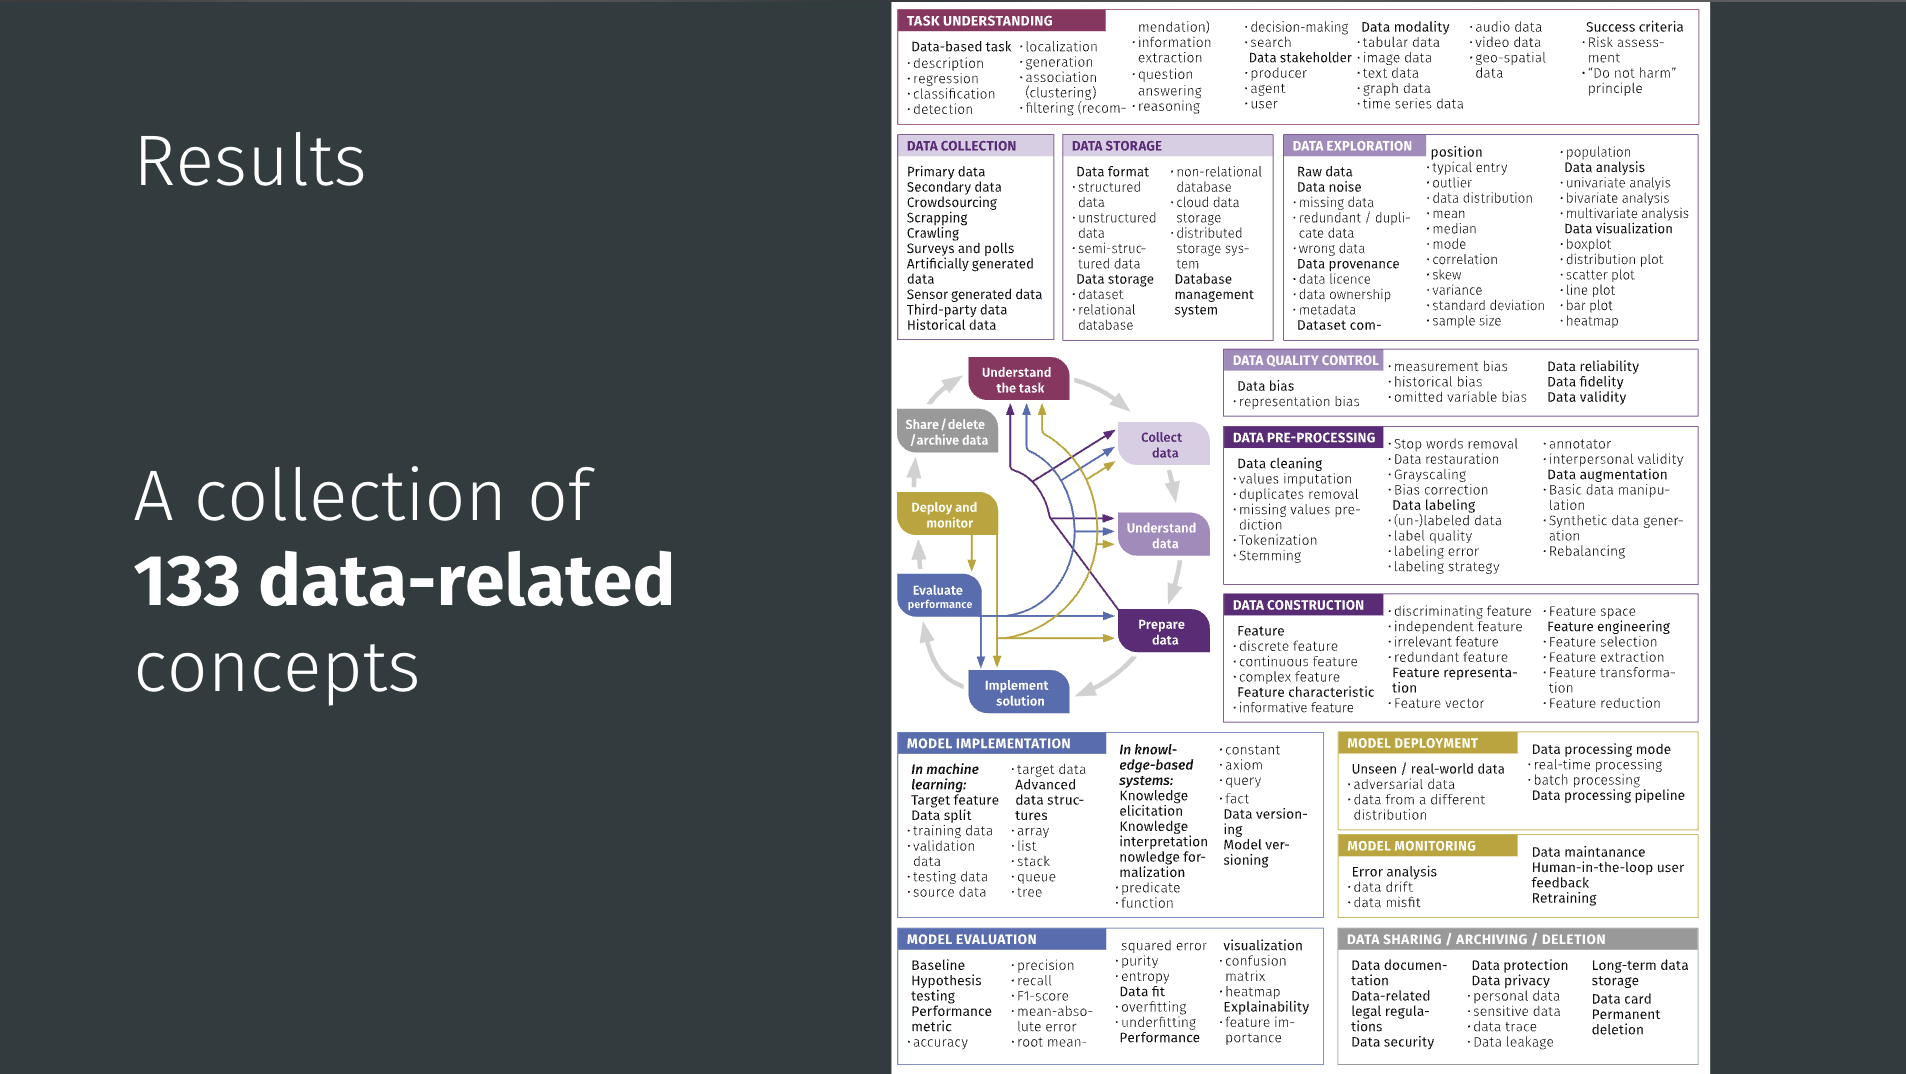
A collection of 133 key data-related concepts. These concepts are organised according to the eight stages of the data-driven lifecycle and provide the foundational vocabulary for teaching AI education.
Making it teachable
Viktoriya’s team set out to redesign the format so that real data work could happen within ordinary lessons. They ended up with three “Data Case Study” architectures, each using authentic datasets and domain questions. The materials are supported by Orange 3, an unplugged machine learning and data visualisations tool familiar to the teachers participating. Variants emerged across three design cycles to address specific challenges, but teachers choose among them based on learning objectives and class context.
- Bottom-up: Students create a workflow step by step (e.g. import, inspect, clean, transform, split, train, evaluate). This approach is excellent for procedural fluency, but teachers reported an over-emphasis on operating Orange and too little reflection on the lifecycle unless explicit reflection is added.
- Top-down: Students start from a prepared workflow, read plots, infer the role of each branch, identify issues in the data/practices, and justify changes. This architecture directly counters the reflection gap seen in bottom-up and leans into reasoning rather than routine.
- Puzzle-like: Using “widgets,” visualisations of data tables, that stand for parts of a data pipeline, students rebuild a valid flow collaboratively. This encourages discussion, works without devices, and makes thinking visible.
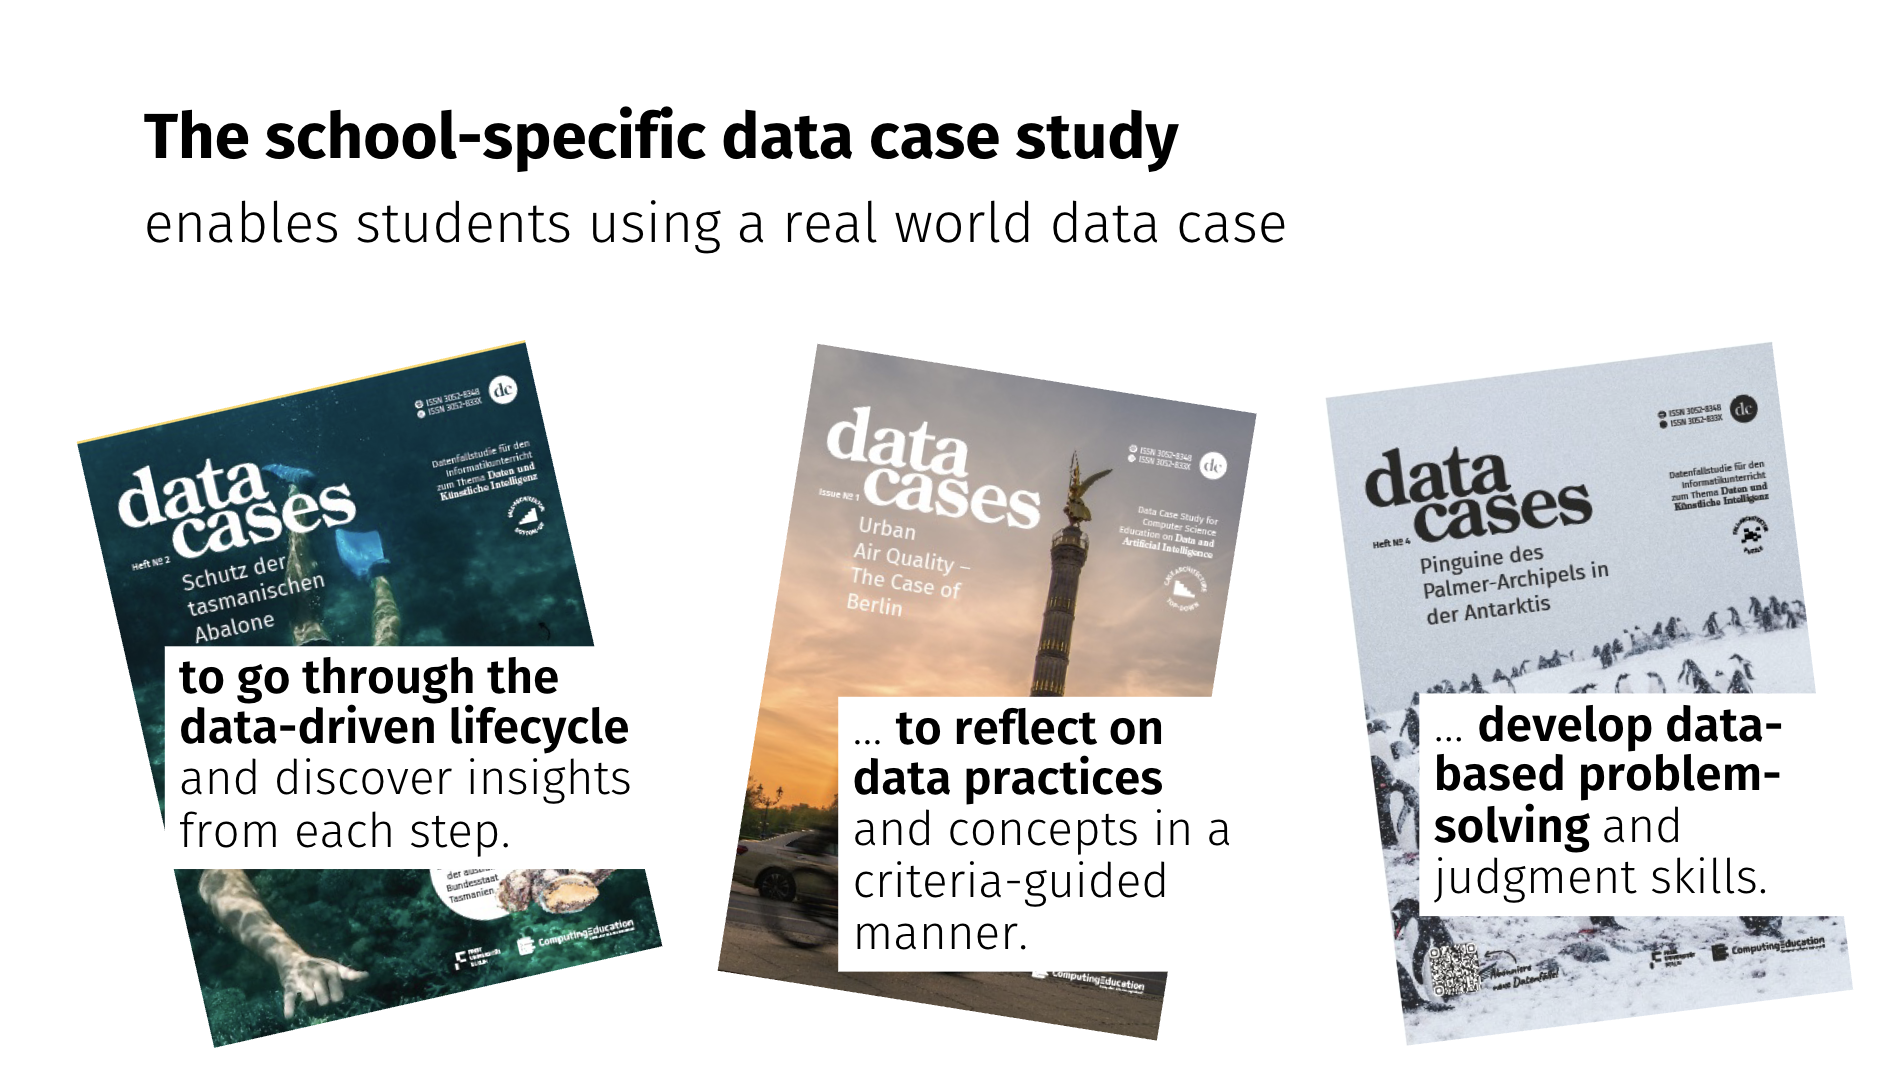
The data case study method uses real-world data and context to help students achieve three key learning outcomes: go through the data-driven lifecycle, reflect on data practices and concepts in a criteria-guided manner, and develop data-based problem-solving and judgment skills.
What happened in the German classrooms
Viktoriya’s team ran three design cycles with small groups in Germany, with students aged 14 to 15. Each cycle lasted around 48 hours of teaching. Because participating teachers already knew Orange 3, the emphasis was on pedagogy rather than software training.
The projects drew on manageable real-world data: spreadsheets, time-series sets, a few geographical samples. Two examples are:
- Forecasting Berlin air quality – Students explored how data quality, feature choice, and evaluation metrics shape predictions, then argued which model best answered the civic question.
- Classifying Tasmanian abalone – A deceptively simple dataset that invites talk about imbalance, feature engineering, and what counts as “good enough” accuracy.
Some groups experimented with collecting their own sensor data, a plan that occasionally failed when the hardware didn’t cooperate. However, even that became part of the lesson: reliability, risk, and missing data are real features of data science, not mistakes to hide.
Student work reflected the three architectures. In the bottom-up groups, guided builds produced complete workflows and concise reflections, while top-down groups submitted annotated screenshots and critiques, and the puzzle-based lessons ended with posters and verbal presentations. Across them all, assessment focused on reasoning: not whether the “right” model appeared, but whether students could explain the stage they were in and justify their choices.
Teaching resources
Everything Viktoriya described is open and classroom-ready (currently in German). The computingeducation.de/proj-datacases hub hosts teacher guides, student tasks, and sample Orange 3 files. The growing library of data cases covers topics from climate data to air quality analytics.
Why it matters now
In the UK, a curriculum review has been recently released and along with the Government’s response. Across Europe and beyond, education systems are racing to add AI content to their curricula. Tools will come and go, and benchmarks will keep moving. What endures is the capacity to reason about data: to know what stage of work you’re in, what evidence supports your decisions, and what trade-offs you’re making. That is why Viktoriya’s contribution is unique — it gives teachers a map, a shared vocabulary, and practical ways to make data visible and the focus of discussion in schools.
You can read this blog to see how we’ve used Viktoriya’s framework in our work designing a data science curriculum for schools.
Join our next seminar
Join us at our seminar on Tuesday 27 January from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about how to teach about neural networks in Junior High Schools in Ghana.
To sign up and take part, click the button below. We’ll then send you information about joining.
We hope to see you there. This will be the final seminar in our series on teaching about AI and data science — the next series focuses on how to teach about applied AI across subjects and disciplines.
You can view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.
Teachers in England, take part in our new data science study
We’re looking for upper key stage 2 teachers in England who want to join our new collaborative study exploring how to teach learners aged 9 to 11 about data-driven computing. The study will look at:
- How Computing teachers currently approach topics related to data-driven computing
- What key ideas pupils need to understand
- How pupils make sense of data and probability
Our aim for the study is to find practical ways for Computing teachers to build young people’s confidence in working with data in lessons. The study will involve two workshops held throughout 2026.
Register your interest by filling in this form.
The post How to put data first in K–12 AI education by using data case studies appeared first on Raspberry Pi Foundation.
Adreno Gen 8 Vulkan Graphics Merged For Mesa 26.0 To Support The Snapdragon X2
Merged in time for the upcoming Mesa 26.0 release is the merging of Vulkan driver support for the Qualcomm Adreno Gen 8 graphics support that is notably used by the new Snapdragon X2 laptop SoCs as well as the Snapdragon 8 Elite Gen 5…
DragonFlyBSD Now Allows Optional AMD GCN 1.1 Support In AMDGPU Driver
DragonFlyBSD’s AMDGPU kernel graphics driver continues to be a port of the AMDGPU Linux kernel driver. Their latest porting effort for AMD graphics on DragonFlyBSD is now enabling optional support for the GCN 1.1 “Sea Islands (CIK) graphics processors on this modern alternative to the prior Radeon kernel driver…
ESP32-E22 debuts with tri-band Wi-Fi 6E and dual-mode Bluetooth
Espressif Systems has announced the ESP32-E22, its first Wi-Fi 6E connectivity co-processor and the starting point of a new product line targeting higher-performance wireless designs. The company positions the device as a radio co-processor that offloads Wi-Fi and Bluetooth networking functions from a host processor, allowing the host to focus on application-level tasks. ESP32-E22 integrates […]
Can I clean my drivetrain without worrying about squeaky discs?
In our Tech Q&A series, we tackle cycling queries – big or small, complex or simple – with insights from the BikeRadar team and trusted industry experts. Next up, a reader wants to know how they can clean and lubricate their drivetrain without contaminating their rotor.
Is there a practical way to clean and lubricate the drivetrain on my disc-brake equipped bike without having to remove the back wheel, to avoid contaminating the rear rotor?
A reader, via email
Absolutely, but it requires you to take care.
Simon von Bromley points out that one solution is to simply wax your chain rather than using off-the-shelf lubes, because this cuts out the need for cleaning and re-lubing. But that’s not the question we’ve been asked.
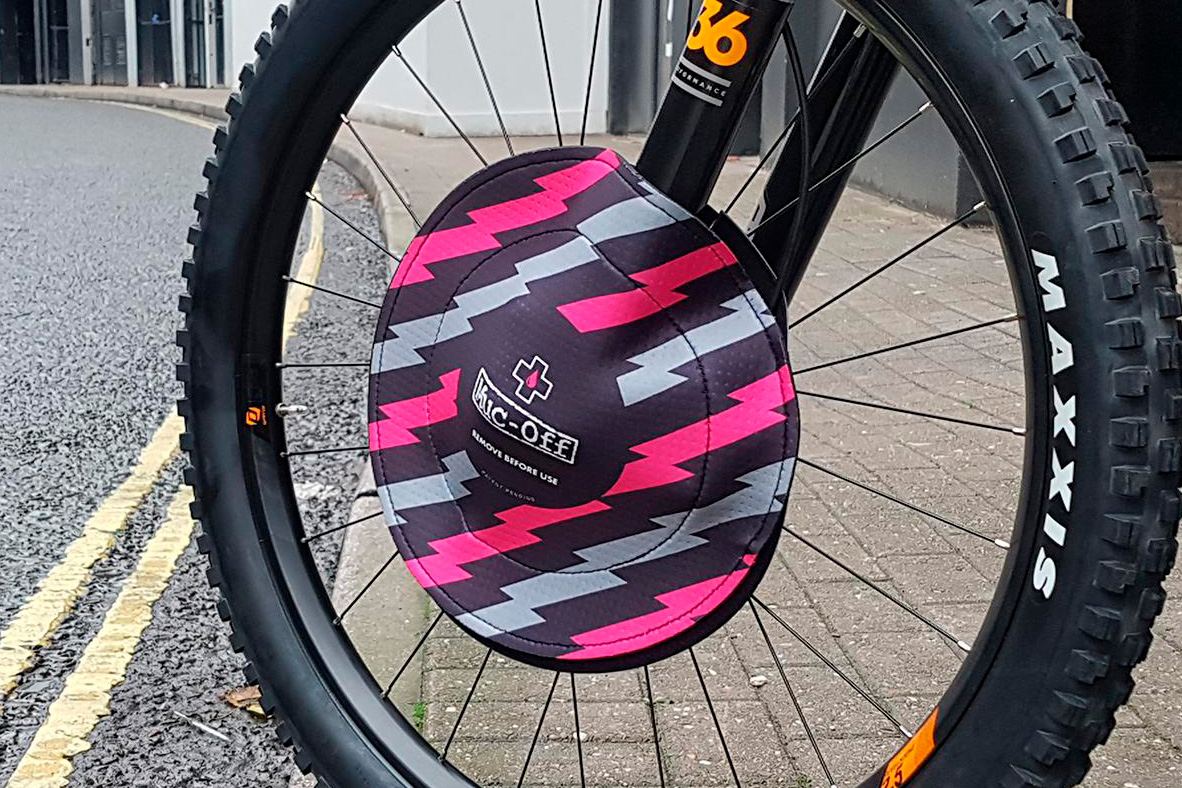
Digital editor Jack Luke explains there are covers you can buy for brake rotors (from Muc-Off, for example) or, if you want to save some cash, you can tie a plastic bag over the disc – or use a piece of cardboard to shield it.
However, these aren’t strictly necessary. Instead, you simply need to take care not to overspray any aerosols on the rotor.
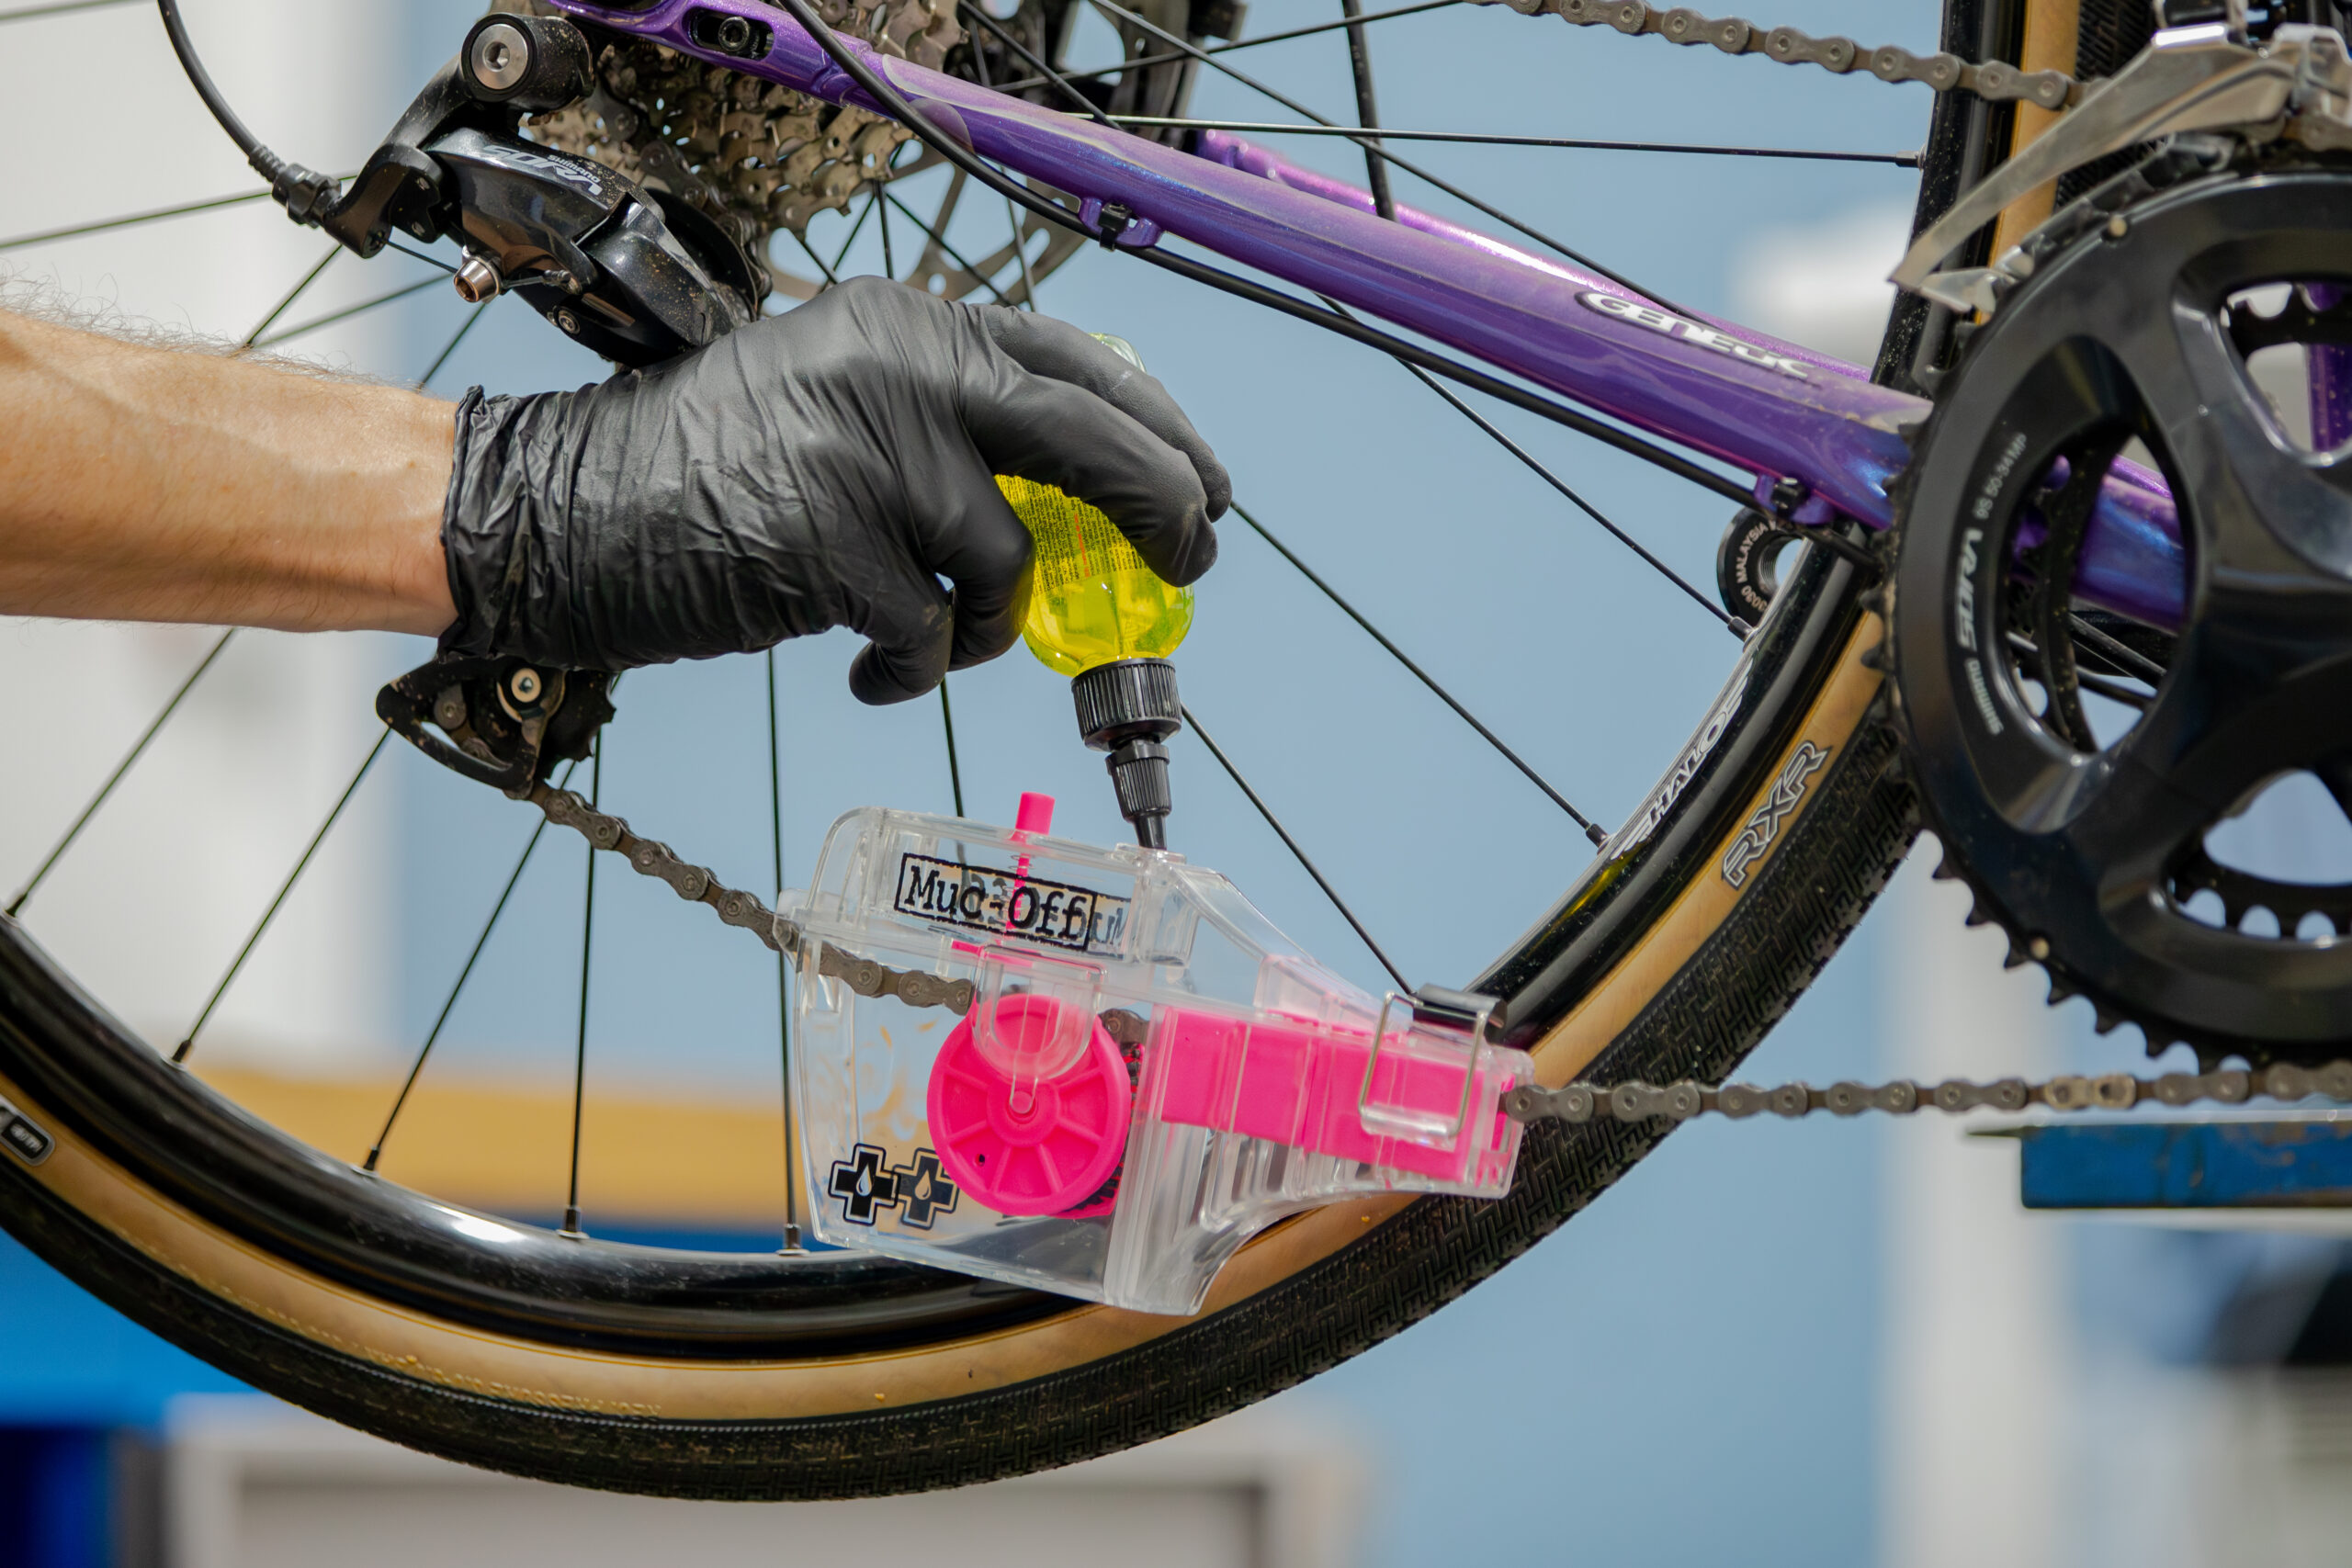
When applying degreaser, either use a brush or spray it downwards so it doesn’t find its way into the brake caliper or onto the disc.
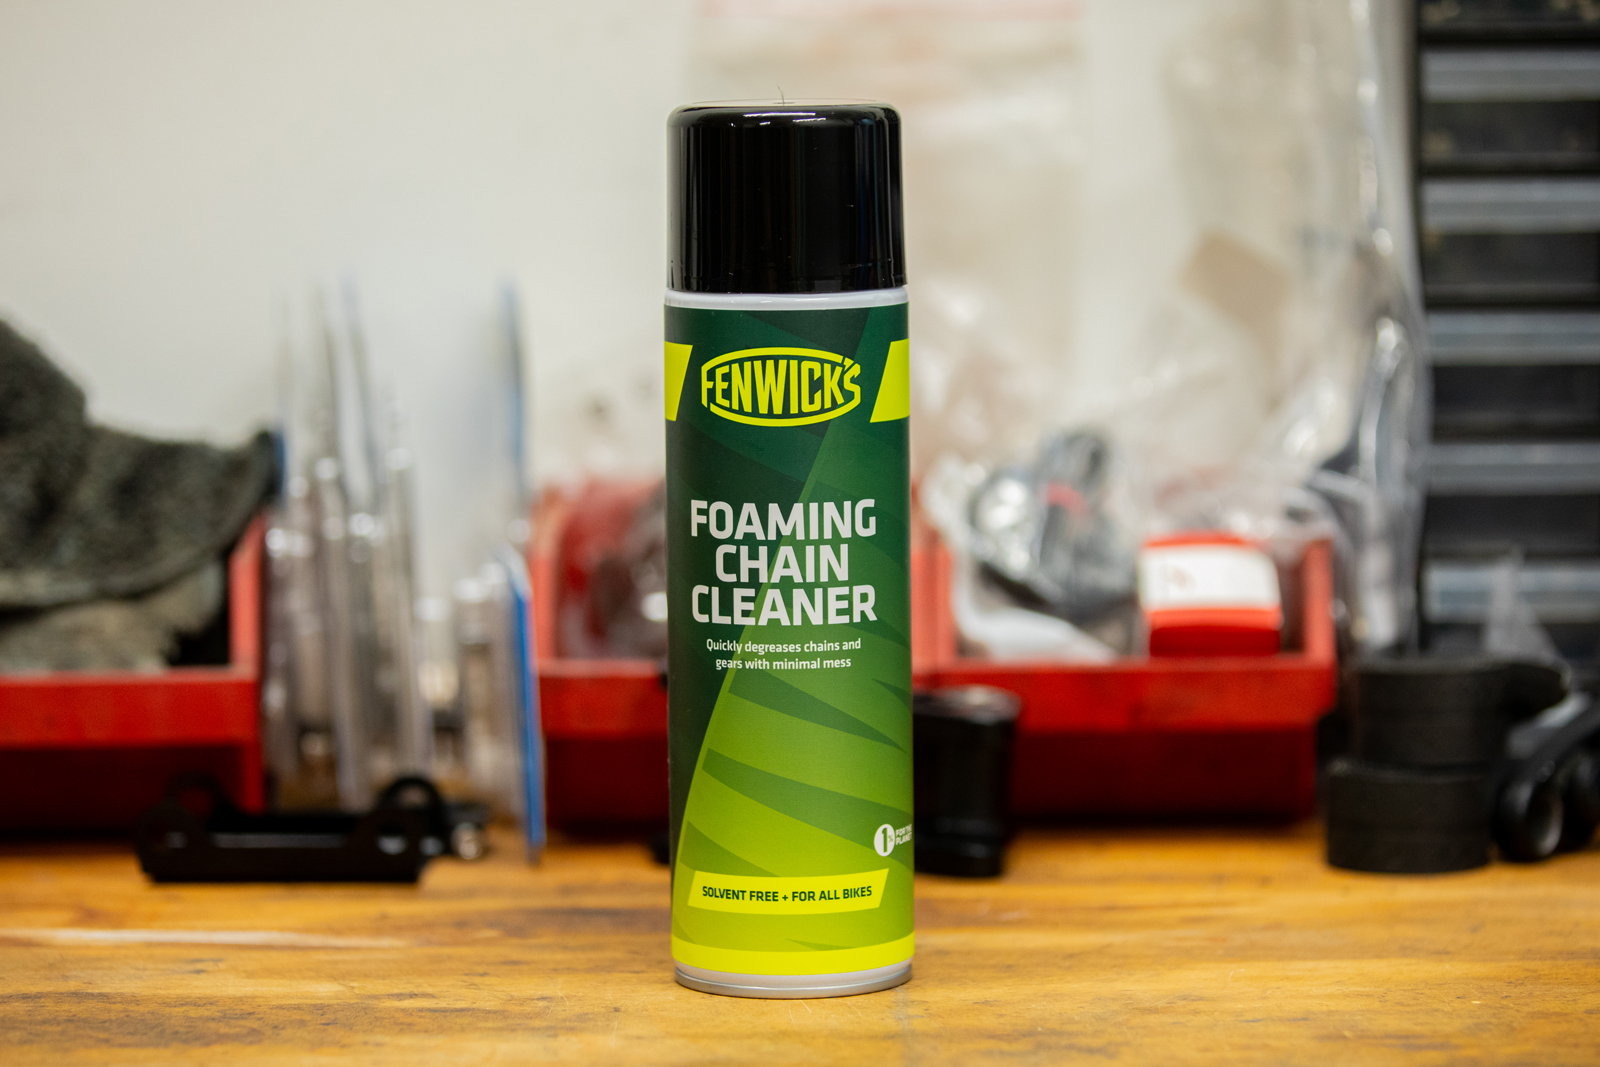
Using a foaming chain cleaner (for example, Fenwicks) will also reduce the risk of contamination, because the foam settles directly onto the chain and cassette.
It’s a similar situation when applying lube.
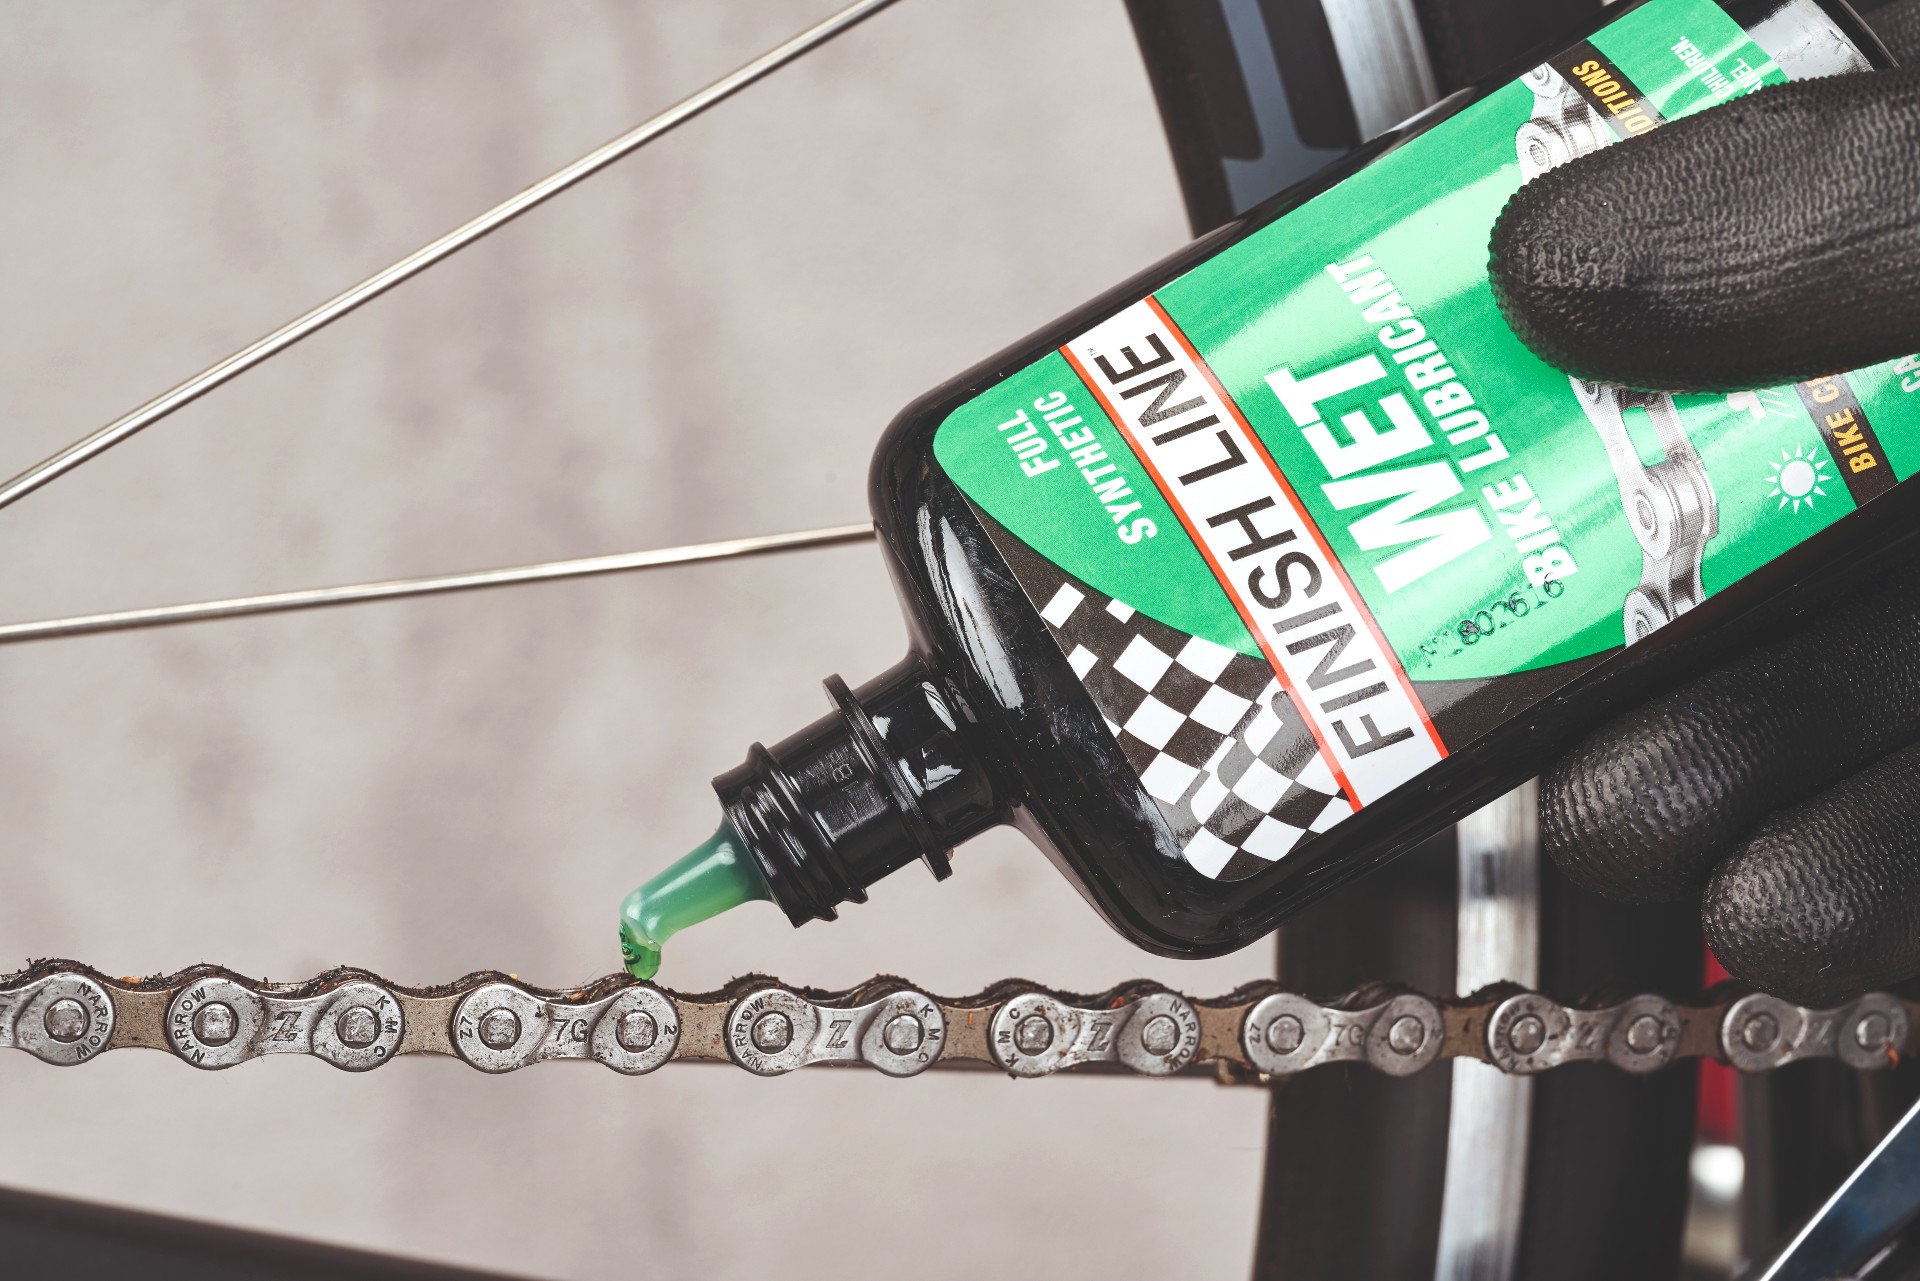
Make sure to hold the bottle close to the chain links and squeeze drips of lubricant onto the rollers as you turn the cranks backwards.
You can then use a rag to wipe off any excess.
MX Linux 25.1 Is Out with Dual-Init Support, Debian 13.3 Base, and Linux 6.18 LTS
The MX Linux team announced today the general availability for download of MX Linux 25.1 as the first update in the MX Linux 25 “Infinity” series of this Debian-based distribution featuring Xfce, KDE Plasma, and Fluxbox flavors.
MultiCM Flasher enables parallel programming of Raspberry Pi Compute Modules
Recently featured on Tindie, the MultiCM Flasher is a parallel programming device designed to flash multiple Raspberry Pi Compute Module variants simultaneously. The device supports eMMC-based Compute Modules across several generations, including CM3, CM3+, CM4S, CM4, and CM5. The MultiCM Flasher is designed for programming up to seven Compute Modules in parallel, with support for […]
Bank of England ‘Must Plan For a Financial Crisis Triggered By Aliens’
A former Bank of England analyst has urged contingency planning for a potential financial shock if the U.S. government were to confirm the existence of extraterrestrial intelligence. The argument is that “ontological shock” alone could destabilize confidence and trigger crisis dynamics. The Independent reports: [Helen McCaw, who served as a senior analyst in financial security at the UK’s central bank and worked for the Bank of England for 10 years until 2012] said politicians and bankers can no longer afford to dismiss talk of alien life, and warned a declaration of this nature could trigger bank collapses. She reportedly said: “The United States government appears to be partway through a multi-year process to declassify and disclose information on the existence of a technologically advanced non-human intelligence responsible for Unidentified Anomalous Phenomena (UAPs).”
“If the UAP proves to be of non-human origin, we may have to acknowledge the existence of a power or intelligence greater than any government and with potentially unknown intentions.” Her warning comes as senior American officials have recently indicated their belief in the possibility of alien life. […] Ms McCaw said: “UAP disclosure is likely to induce ontological shock and provoke psychological responses with material consequences … There might be extreme price volatility in financial markets due to catastrophising or euphoria, and a collapse in confidence if market participants feel uncertain on how to price assets using any of the familiar methods.”
The former Bank of England worker explained there might be a rush towards assets such as gold or other precious metals, and government bonds, which are perceived as “safe.” Alternatively, she said precious metals might lose their status as perceived safe assets if people speculate that new space-faring technologies will soon increase the supply of precious metals. The article cites a recent UFO documentary, The Age of Disclosure, where 34 U.S. government insiders, including those from the military and intelligence community officials, share insights about the governments work with UAP. Per the film’s description, the documentary “reveals an 80-year global cover-up of non-human intelligent life and a secret war among major nations to reverse-engineer advanced technology of non-human origin.”


Read more of this story at Slashdot.
The Fastest Human Spaceflight Mission In History Crawls Closer To Liftoff
An anonymous reader quotes a report from Ars Technica: Preparations for the first human spaceflight to the Moon in more than 50 years took a big step forward this weekend with the rollout of the Artemis II rocket to its launch pad. The rocket reached a top speed of just 1 mph on the four-mile, 12-hour journey from the Vehicle Assembly Building to Launch Complex 39B at NASA’s Kennedy Space Center in Florida. At the end of its nearly 10-day tour through cislunar space, the Orion capsule on top of the rocket will exceed 25,000 mph as it plunges into the atmosphere to bring its four-person crew back to Earth. “This is the start of a very long journey,” said NASA Administrator Jared Isaacman. “We ended our last human exploration of the moon on Apollo 17.”
[…] “We really are ready to go,” said Wiseman, the Artemis II commander, during Saturday’s rollout to the launch pad. “We were in a sim [in Houston] for about 10 hours yesterday doing our final capstone entry and landing sim. We got in T-38s last night and we flew to the Cape to be here for this momentous occasion.” The rollout began around sunrise Saturday, with NASA’s Space Launch System rocket and Orion capsule riding a mobile launch platform and a diesel-powered crawler transporter along a throughway paved with crushed Alabama river rock. Employees, VIPs, and guests gathered along the crawlerway to watch the 11 million-pound stack inch toward the launch pad. The rollout concluded about an hour after sunset, when the crawler transporter’s jacking system lowered the mobile launch platform onto pedestals at Pad 39B.
The rollout keeps the Artemis II mission on track for liftoff as soon as next month, when NASA has a handful of launch opportunities on February 6, 7, 8, 10, and 11. The big milestone leading up to launch day will be a practice countdown or Wet Dress Rehearsal (WDR), currently slated for around February 2, when NASA’s launch team will pump more than 750,000 gallons of super-cold liquid hydrogen and liquid oxygen into the rocket. NASA had trouble keeping the cryogenic fluids at the proper temperature, then encountered hydrogen leaks when the launch team first tried to fill the rocket for the unpiloted Artemis I mission in 2022. Engineers implemented the same fixes on Artemis II that they used to finally get over the hump with propellant loading on Artemis I. […] If the launch does not happen in February, NASA has a slate of backup launch dates in early March.


Read more of this story at Slashdot.
Banana Pi’s BPI-CM6 compute module runs on SpacemiT K1 RISC-V processor
Banana Pi’s BPI-CM6 is a compute module based on the SpacemiT K1 octa-core RISC-V processor. First revealed in April 2025, the module is now available for purchase from multiple sources and is described as a compact compute platform for edge computing, robotics, industrial control, and network storage applications. The BPI-CM6 adopts a 40 × 55 […]
The World’s Longest-Running Lab Experiment Is Almost 100 Years Old
alternative_right shares a report from ScienceAlert: It all started in 1927, when physicist Thomas Parnell at the University of Queensland in Australia filled a closed funnel with the world’s thickest known fluid: pitch, a derivative of tar that was once used to seal ships against the seas. Three years later, in 1930, Parnell cut the funnel’s stem, like a ribbon at an event, heralding the start of the Pitch Drop Experiment. From then on, the black substance began to flow. At least, that is, in a manner of speaking. At room temperature pitch might look solid, but it is actually a fluid 100 billion times more viscous than water.
It took eight years for the first droplet to finally hit the beaker below. Then, they dripped at a cadence of once every eight years or so, slowing down only after air conditioning was installed in the building in the 1980s. Today, 96 years after the funnel was cut, only nine drops in total have seeped out. The last was in 2014. Scientists expect another will fall sometime in the 2020s, but they are still waiting. No one has ever actually seen a droplet fall directly, despite all the watchful eyes. The experiment is now live-streamed, but various glitches in the past meant that each fateful moment has slipped us by.


Read more of this story at Slashdot.
X.Org Server May Create A New Selective Git Branch With Hopes Of A New Release This Year
A proposal has been laid out for a new X.Org Server “main” Git branch to house their development going forward and cleaning up the development lapses over the past few years. Ultimately the hope is for having a new cleaned-up X.Org Server and XWayland Git branch for shipping new releases in 2026…
Germany’s EV Subsidies Will Include Chinese Brands
Germany is reinstating EV subsidies after a sharp sales drop, rolling out a 3 billion-euro program offering 1,500-6,000 euros per buyer starting in May and running through 2029. Unlike some neighboring countries, the incentives are open to all manufacturers with a focus on low- and middle-income households. From a report: “I cannot see any evidence of this postulated major influx of Chinese car manufacturers in Germany, either in the figures or on the roads — and that is why we are facing up to the competition and not imposing any restrictions,” German Environment Minister Carsten Schneider said at a Monday press conference. The decision is a major boon for affordable Chinese automakers like BYD that are steadily gaining ground in the European market, [Bloomberg noted].
Germany’s green-light for Chinese EVs stands in stark contrast to other nations’ approaches. In the UK, subsidies introduced last year effectively excluded Chinese battery-powered vehicles, while France’s so-called social leasing scheme includes similar restrictions. […] Germany maintains strong diplomatic ties with China. German automakers are among the most significant players in China’s automotive industry. Over the past years, China’s policies — including purchase subsidies and purchase tax reductions — have not excluded models or automakers from specific countries. Whether German automakers like Volkswagen or American automakers like Tesla, all enjoy national-level purchase incentive policies in China on par with domestic automakers.


Read more of this story at Slashdot.
Nvidia leans on emulation to squeeze more HPC oomph from AI chips in race against AMD
AMD researchers argue that, while algorithms like the Ozaki scheme merit investigation, they’re still not ready for prime time.Double precision floating point computation (aka FP64) is what keeps modern aircraft in the sky, rockets going up, vaccines effective, and, yes, nuclear weapons operational. But rather than building dedicated chips that process this essential data type in hardware, Nvidia is leaning on emulation to increase performance for HPC and scientific computing applications, an area where AMD has had the lead in recent generations.…
A Second US Sphere Could Come To Maryland
Sphere Entertainment plans to build a second U.S. Sphere near Washington, D.C., with a smaller 6,000-seat “mini-Sphere” proposed for National Harbor in Maryland. The venue would retain the signature LED exterior and immersive 4D tech of the Las Vegas Sphere, just at a more compact scale. The Verge reports: The second US sphere would be built in an area known as National Harbor in Prince George’s County, Maryland. Located along the Potomac River, National Harbor currently features a convention center, multiple hotels, restaurants, and shops. While Abu Dhabi plans to build a sphere as large as the one in Las Vegas, the National Harbor venue would be one of the first mini-Sphere venues announced last March.
Its capacity would be limited to 6,000 seats instead of over 17,000. But the smaller Sphere would still be hard to miss with an exterior LED exosphere for showcasing the “artistic and branded content” that helped make the original sphere a unique part of the Las Vegas skyline. The inside of the mini-Sphere will feature a high-resolution 16,000 by 16,000 pixel wrap-around screen, the company’s immersive sound technology, haptic seating, and “4D environmental effects.” For the AI-enhanced version of The Wizard of Oz currently playing in Las Vegas, audiences experience effects like wind, fog, smells, and apples falling from the ceiling.


Read more of this story at Slashdot.
Nvidia Contacted Anna’s Archive To Secure Access To Millions of Pirated Books
An anonymous reader quotes a report from TorrentFreak: NVIDIA executives allegedly authorized the use of millions of pirated books from Anna’s Archive to fuel its AI training. In an expanded class-action lawsuit that cites internal NVIDIA documents, several book authors claim (PDF) that the trillion-dollar company directly reached out to Anna’s Archive, seeking high-speed access to the shadow library data. […] Last Friday, the authors filed an amended complaint that significantly expands the scope of the lawsuit. In addition to adding more books, authors, and AI models, it also includes broader “shadow library” claims and allegations. The authors, including Abdi Nazemian, now cite various internal Nvidia emails and documents, suggesting that the company willingly downloaded millions of copyrighted books. The new complaint alleges that “competitive pressures drove NVIDIA to piracy,” which allegedly included collaborating with the controversial Anna’s Archive library.
According to the amended complaint, a member of Nvidia’s data strategy team reached out to Anna’s Archive to find out what the pirate library could offer the trillion-dollar company “Desperate for books, NVIDIA contacted Anna’s Archive — the largest and most brazen of the remaining shadow libraries — about acquiring its millions of pirated materials and ‘including Anna’s Archive in pre-training data for our LLMs,'” the complaint notes. “Because Anna’s Archive charged tens of thousands of dollars for ‘high-speed access’ to its pirated collections [] NVIDIA sought to find out what “high-speed access” to the data would look like.”
According to the complaint, Anna’s Archive then warned Nvidia that its library was illegally acquired and maintained. Because the site previously wasted time on other AI companies, the pirate library asked NVIDIA executives if they had internal permission to move forward. This permission was allegedly granted within a week, after which Anna’s Archive provided the chip giant with access to its pirated books. “Within a week of contacting Anna’s Archive, and days after being warned by Anna’s Archive of the illegal nature of their collections, NVIDIA management gave ‘the green light’ to proceed with the piracy. Anna’s Archive offered NVIDIA millions of pirated copyrighted books.” The complaint states that Anna’s Archive promised to provide NVIDIA with access to roughly 500 terabytes of data. This included millions of books that are usually only accessible through Internet Archive’s digital lending system, which itself has been targeted in court. The complaint does not explicitly mention whether NVIDIA ended up paying Anna’s Archive for access to the data.
Additionally, it’s worth mentioning that NVIDIA also stands accused of using other pirated sources. In addition to the previously included Books3 database, the new complaint also alleges that the company downloaded books from LibGen, Sci-Hub, and Z-Library. In addition to downloading and using pirated books for its own AI training, the authors allege NVIDIA distributed scripts and tools that allowed its corporate customers to automatically download “The Pile”, which contains the Books3 pirated dataset.


Read more of this story at Slashdot.
How to Install and Use Scala on Linux
In this article, you will learn the advantages of using the Scala programming language and how to install it on your preferred Linux system with a practical example.